The AI advantage that compute can’t buy
INTRODUCING THE 8TH GENERATION OF THE SENSIA ENGINE
Understanding what matters across hundreds of thousands of consumer reviews, identifying opportunities and examining the evidence behind them: this ambition has guided Sensia from the outset.
Today, we introduce the 8th generation of our engine. It combines our latest specialised AI models with advances in relevant information selection, deeper analysis and conversational exploration.
This major update is available today to all our clients, across all our offerings and programmes
Teams can move from a question about an entire market to a closer examination of a brand, product or experience, while retaining the link to the source reviews.
We put this technology to the test: the main strategic findings and their order of priority remained consistent as the AI moved from focused selections to substantially larger volumes of evidence. The results demonstrate Sensia’s ability to identify what matters within a much larger body of information—and illuminate where value is built as investment in AI accelerates.
- Brand, marketing, innovation and insights — What makes an analysis worth acting on? Four things to demand from AI-powered consumer insights →
- AI, data and transformation — Where should you invest, and where can specialist capabilities help? Explore the choices behind enterprise AI programmes →
Historic investment. The question of value
The AI industry is investing on a historic scale. Combined 2026 spending by the largest cloud providers has passed $700 billion, according to Reuters’ Morning Bid as reported by 24/7 Wall St. (Yahoo Finance). These investments expand the capabilities available. The question is where they will produce returns commensurate with the resources committed.
There are three distinct levels of value creation. Infrastructure provides compute. Model providers turn that compute into general AI capabilities. Enterprises integrate those capabilities into business processes to achieve practical outcomes. Each must establish its own economic return, at a different pace.
For infrastructure, Gartner puts the challenge in figures. To cover announced capital spending, financing costs and a 12% return on invested capital, AI data-centre owners would need $8.5 trillion in cumulative revenue through 2030. Gartner forecasts no more than $3.6 trillion in AI revenue attributable to those data centres over the period (Gartner).
That gap highlights the importance of the uses that will make these capabilities economically productive. Infrastructure is being financed before all the applications expected to pay for it have found their place.
Hardware renewal adds another dimension. One Princeton analysis argues that frontier AI chips retain their economic edge for one to three years, compared with the five or six years used in company accounts; its author presents the analysis as work in progress (Princeton CITP). Older generations can nevertheless remain profitable: Ornn reported A100 occupancy among tracked providers rising from 74% to 90% between March and September 2026 (Ornn). Matching capability to the task is becoming an economic skill in its own right.
Microsoft’s results illustrate both growing demand and the weight of investment. Azure grew 41% and passed $100 billion in annual revenue, while cloud gross margin fell to 66%, reflecting continued investment in AI infrastructure (Microsoft annual report 2026). These figures cover the broader cloud business; they do not directly measure the return on enterprise AI use.
For organisations adopting AI, the move from experimentation into everyday work remains decisive. MIT’s 2025 study of enterprise generative AI programmes highlighted difficulties integrating systems into real workflows (Computing).
The investment question is therefore practical: which capabilities create value in a particular use, which should an organisation develop, and where should it work with a specialist?
Reading more is not learning more
Consider the field Sensia works in: understanding what consumers say about the products in a category, across a whole market. A single dataset can contain hundreds of thousands of reviews, covering many products and several languages. Some describe a specific experience; others repeat a general assessment. They do not all answer the same question.
The intuitive response is to give a powerful AI model as much material as possible. But every model can process only a limited amount of text at a time. And even as that capacity grows, reading more does not guarantee a better understanding of what matters.
Research by Chroma found that models do not always use long inputs evenly, and that reliability can decline as input volume increases, depending on the models and tasks tested (Chroma).
The challenge begins upstream: how do you identify the information that actually answers the question? How do you organise it, put it in perspective and preserve the reviews that allow the analysis to be examined?
Selecting well requires understanding first. That is the capability Sensia has invested in from the outset.
How Sensia turns reviews into useful knowledge
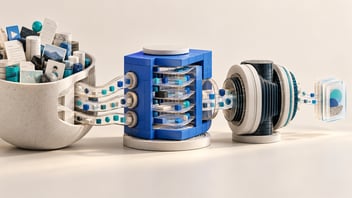
Before a synthesis is written, the Sensia engine analyses reviews to understand the topics discussed, products involved and opinions expressed. It uses around twenty proprietary AI models, each specialised in the language of a category, from skincare to pet food.
This understanding provides the foundation for measurement and the selection of relevant information for each question. An analysis of consumer expectations, a competitive comparison and an examination of product experience do not require exactly the same evidence.
The engine then supplies this prepared material to a general-purpose AI model capable of reasoning, synthesis and writing. Teams can explore the findings through conversation and examine the reviews supporting them.
Specialised understanding, measurement and evidence preparation form Sensia’s own technological foundation. General-purpose models complement that foundation and can evolve as the wider AI industry advances.
The architecture of the Sensia engine. The methods used to understand data, select evidence and prepare it for analysis are proprietary.
What the 8th generation makes possible
This generation advances the whole engine. Our specialised models reach their eighth generation, alongside developments in evidence preparation and deeper analysis.
The engine has greater flexibility to adapt reading depth to each question. An initial reading uses a focused selection; a question requiring more detail can draw on several thousand reviews.
This flexibility benefits from growth in the amount of text general-purpose models can receive at once, known as their “context window”. It gives Sensia more room to investigate a question in depth, building on its established expertise in evidence selection.
The decision is what deserves deeper investigation. Additional material can enrich the analysis, but also adds cost and time. We therefore measured what it contributes to the findings and priorities already identified through focused selections.
Putting the 8th generation to the test
We selected five production analyses from three of our largest and most heterogeneous datasets, in skincare and pet food.
We varied the number of reviews examined, from a few hundred to around 9,000 per section, using the same general-purpose model. On two sections, we also compared our production configuration with a high-end reasoning model receiving more evidence.
All configurations used data prepared by Sensia. The tests addressed three questions.
Do focused selections already identify the essential findings and priorities?
Using a limited selection of reviews, Sensia already identified the main strategic findings and their order of priority, confirmed when the AI examined substantially more material. We extended reading to the general-purpose model’s maximum capacity to put that selection to the test.
Across the five analyses and six reading depths, the core opportunity areas, leading choice driver and central trade-offs remained consistent in the analyses where they were assessed.
Deeper reading enriched some supporting material with additional product references, further detail or longer consumer quotations. It added nuance while confirming the main strategic directions and their order of priority.
Across the same twenty sections, general-purpose model usage cost at maximum capacity was around thirteen times higher than for the configuration of around 1,000 reviews.
This comparison shows the value of being able to investigate further while understanding what the focused selection already reveals.
Does the selection leave out products carrying substantial relevant feedback?
A limited selection could omit products accounting for a substantial share of reviews on the subject. To examine this risk, we reconstructed the full pool of relevant reviews for four questions, then measured the weight of the products represented in the samples.
At around 1,500 selected reviews per question, represented products accounted for 98.1%–99.5% of total relevant review volume.
This provides a second perspective on Sensia’s selection: the samples include the products carrying almost all that volume. It complements the comparison of findings and priorities described above.
Depth is adjusted to the question and the contribution of additional evidence. A particular product or topic may also justify a targeted examination.
Does a more powerful reasoning model change the findings?
On two sections, we compared our production configuration with a high-end general-purpose model configured for extensive reasoning. It received around twice as much evidence, also prepared by Sensia.
Both configurations produced comparable main findings. The reference model added some nuance in wording; no new major decision was identified in the sections examined. Its usage cost was more than thirty times higher
We explore the implications for business teams in Four things to demand from AI-powered consumer insights. Architecture, resource and partnership choices are examined in our companion article on enterprise AI programmes.
Expertise built before synthesis begins
These results demonstrate the value of work performed before an analysis is written: understanding what the data expresses, measuring the patterns observed and preparing relevant information for each question.
Selection is the result of that specialised understanding. In the cases studied, it already supported the main findings and priorities recovered with substantially greater volumes and costs.
This expertise is built category by category. It rests on proprietary models, qualified data, measurement methods and sustained evaluation and maintenance. The 8th generation extends that investment and how it can be used.
For enterprises integrating AI into business processes, the decision also concerns these capabilities: which do they want to develop and maintain, and where can they work with a specialist? Sensia provides this foundation of consumer understanding, helping teams advance their AI programmes.
This architecture also allows us to benefit from advances in general-purpose models. Domain understanding remains within Sensia’s technologies; the model responsible for reasoning and synthesis can evolve after its results have been evaluated.
The move from GPT-5.4 to Luna illustrates this freedom to evolve the general-purpose model while retaining Sensia’s technological foundation.
The aim is to bring clients the benefits of progress in AI while retaining and strengthening the specialised understanding that makes the analysis valuable.
An advantage that compounds
Investment in models and infrastructure will continue to expand the capabilities available. Sensia and its clients will benefit.
As those capabilities spread, the expertise needed to turn data into useful knowledge becomes increasingly important. That is what we have developed from the outset: understanding markets, selecting relevant information and enabling teams to explore its implications.
The 8th generation of the engine takes that ambition further.
"Our ambition is to help everyone understand what matters to consumers and turn that understanding into ideas. With Sensia, we want to make that ability available across the organisation, so every team can recognise opportunities and act with confidence."
Antoine Poupel, CEO, Sensia
That is the advantage we build, generation after generation.
- For brand, marketing, innovation and insights teams: Four things to demand from AI-powered consumer insights
- For AI, data and transformation leaders: Enterprise AI programmes: more data, stronger models or better evidence selection?
About the benchmark: five production analyses, comprising twenty sections, across three reference datasets in skincare and pet food. Analyses were regenerated at six reading depths, up to the general-purpose model’s maximum capacity. Two sections were also compared with a high-end reasoning configuration receiving more evidence: 122 generations in total, October 2026. Selection reach was measured for four questions. Main findings and their order of priority were assessed by comparative reading. The benchmark examines the current engine in several configurations; it is not a controlled comparison with the previous generation. General-purpose model usage costs are calculated using the provider’s published prices and do not represent the total cost of the Sensia platform. Request the detailed benchmark report.