The AI advantage that compute can’t buy
Introducing Sensia Gen 8
Today we are introducing Sensia Gen 8, the new generation of our qualitative intelligence engine. It combines our eighth-generation specialised models with advances in how the system prepares evidence, selects relevant material and uses larger language-model context windows. Together, these capabilities turn large volumes of fragmented consumer feedback into structured findings that teams can question, explore and trace back to their sources. Our benchmark shows how the engine behaves: small, well-chosen samples reach the products behind almost all the relevant reviews on a question, and the main findings hold from a few hundred reviews up to the full context window of the writing model. As general AI capability expands, it shows where a lasting advantage is built.
What Sensia Gen 8 brings
Gen 8 is not a new language model, and it is not only a new set of our own models. It is a new generation of the whole engine: the specialised models that understand what consumers write, the measurement built on that understanding, the preparation and selection of the material relevant to each question, the use of much larger context windows, and the general-purpose models that synthesise and write. What changes is what the engine as a whole can do.
Why this matters now
The AI industry is answering the question of capability with investment on a historic scale. The combined 2026 spending of the largest cloud providers has passed $700 billion, according to Reuters' Morning Bid as reported by 24/7 Wall St. (Yahoo Finance). That spending raises the capability available to everyone. The open question is what it will earn, and where.
It helps to separate three economies. The first is infrastructure: the companies building data centres and renting out compute. The second is the model vendors, who turn that compute into general-purpose models. The third is the companies that build or buy applications on top of those models, and expect them to produce results. Each has its own return to prove, and the three do not move together.
For the first, Gartner put the question in one comparison in October. To cover their announced capital spending, financing costs and a 12% return on invested capital, AI data-centre owners would need a cumulative $8.5 trillion of revenue through 2030. The AI revenue Gartner expects data centres to generate over the period is no more than $3.6 trillion (Gartner).
The gap does not say that AI will fail. It says that the value will have to come from uses, and that those uses have not yet been proven at the scale of the investment. Infrastructure is being financed ahead of the applications meant to pay for it.
The pace of renewal sharpens the point. One analysis argues that frontier AI chips keep their economic edge for one to three years, against the five or six years used in company accounts; its author presents it as a work in progress (Princeton CITP). Market data point the other way for older hardware: in September, Ornn reported that older GPU generations retain a multi-year earning life on inference, with A100 occupancy among tracked providers rising from 74% to 90% between March and September 2026 (Ornn). Losing the frontier is not the same as becoming unusable. Both observations lead to the same practical point: matching the right level of capability to each task is becoming an economic skill in its own right.
Where AI is woven into real work, value is visible. Microsoft reports that Azure grew 41% and passed $100 billion of revenue for the first time, while its cloud gross margin fell to 66%, driven by continued investment in AI infrastructure (Microsoft annual report 2026). Azure is a whole cloud business, not an AI revenue line, but the direction is clear. Where AI is not woven into work, value is harder to find: MIT's 2025 study of enterprise programmes reported that most generative AI pilots stalled before scaled adoption, and traced the gap mainly to integration with real workflows rather than to model quality (Computing).
For a company applying AI, the question is therefore not how much capability it can access. It is which capabilities create lasting value in its application, and which it should adopt from providers that keep improving them.
Reading more is not learning more
Take the application Sensia works on: understanding what consumers write about the products of a category, across a whole market. A single portfolio can hold hundreds of thousands of reviews, about many products, in several languages and in a vocabulary of its own. Much of it repeats. A large part does not speak to the question being asked.
The intuitive answer is to give a powerful model as much of it as possible. It does not scale: a whole portfolio is many times larger than the largest context window. Research by Chroma documented uneven use of long contexts and declining reliability as inputs grew in the models and tasks it tested (Chroma). It is also the wrong target. Reading more text, and writing a longer report from it, does not automatically mean learning more.
What matters is that the material the model reads carries real signal for the question and reaches the part of the market where consumers actually talk about it. That requires understanding every verbatim before anything is written, then preparing the right evidence for each question. That is the work Gen 8 is built for.
How Gen 8 works
Gen 8 combines two kinds of capability. The first is ours. We train around twenty proprietary vertical models, now in their eighth generation, each specialised in the language of a category, from skincare to pet food. They qualify each verbatim, and the measurement and the selection of evidence are built on that qualification. We do not train large language models; we train the models that understand markets.
General-purpose language models contribute synthesis, reasoning and writing capabilities that continue to improve. Gen 8 applies those capabilities to evidence already prepared for the question.
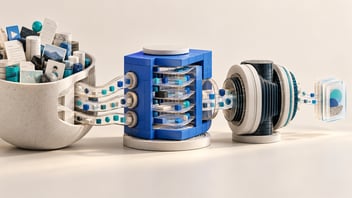
The Sensia Gen 8 engine. How verbatims are qualified, and how evidence is selected and assembled, remains proprietary.
Why larger context windows matter
The writing model used in Gen 8 can be configured to read about a million tokens in a single call, several thousand reviews at once. For an engine like Gen 8, that changes the range of what is possible: the same analysis can run on a focused sample or on several thousand reviews per section, and depth becomes a setting chosen for each question rather than a hard limit.
A larger window is not automatically a better result. Every additional amount of material costs language-model spend and time, and it only matters if it improves something a team cares about: the reach of the evidence, its depth, the stability of the findings. Knowing what each additional amount brings is what turns a larger window into a usable capability. That is what we set out to measure.
Putting Gen 8 to the test
We tested the engine where it is hardest. We took five real analyses on three of the largest and most varied portfolios in our production, in skincare and pet food, and regenerated them with six amounts of material: from the samples our analyses used until now, of a few hundred reviews per section, up to the maximum context window of the same writing model, which reached up to about 9,000 reviews per section. Even that is not a reading of a whole portfolio. On two critical sections, we also compared our configuration with a larger-context reasoning reference. We then asked three questions.
Does a small selection reach what matters?
Selecting a limited sample is only useful if it reaches the products where consumers actually talk about the question. To check, we rebuilt, for four questions, the full pool of relevant reviews across each portfolio, and measured the share of that pool associated with the products present in each sample. This is a measure of the sample's reach across the source data. It is not a percentage of insights recovered.
Across four questions, samples of around 1,500 reviews included products accounting for 98.1% to 99.5% of the relevant review volume.
Reach depends on the question. At around 1,000 reviews it was already between 94% and 99%; the progression differed by question, with one reaching 94.4% at around 1,000 reviews and 98.1% at around 1,500. Depth is therefore a setting adapted to each question, not a fixed rule.
Do the findings hold as depth grows?
Across five production analyses, the main strategic findings remained consistent through all six depth configurations, from a few hundred reviews per section to the writing model's maximum context window, reaching up to around 9,000 reviews. The core opportunity territories, the leading choice driver and the central trade-offs remained consistent in the analyses where they were assessed.
Greater depth expanded the evidence available to support that reading. It could bring additional product references, supporting detail or longer consumer quotations, without changing the main strategic conclusions. For Gen 8, this makes depth a useful capability to adjust to the question: a team can explore further where it needs more evidence, while retaining a consistent reading of the market.
Across the same twenty sections, the maximum-window configuration used about thirteen times the LLM spend of the roughly 1,000-review configuration. The benchmark therefore helps distinguish additional evidence from a change in the main findings, and assess what that additional depth contributes.
Does a more powerful model add decisions?
On two critical sections, a larger-context reasoning reference read about twice as much material, already prepared by Sensia, as our production configuration.
Both configurations produced comparable main findings in the two sections examined. The reasoning reference added some nuance in wording; no new main decision was observed. Its LLM spend was more than thirty times higher. We describe what these results mean for brand teams in a companion article, and for AI and data leaders in another.
What this says about where value is built
The result is not mainly about cost. It supports the view that the quality of an applied AI system can come from a capability that sits before the model: understanding the data of a field well enough to select the right material and give it to the model. That capability is an asset. It is built category by category, improves with each generation of our own models, and does not come with the next model release.
It also changes the relationship with the progress of general-purpose models. Because the understanding of the data lives in models we own, the language model has a defined role in the engine. When a better one arrives, we can adopt it without rebuilding our understanding of each market, checking the results before we do, and its gains go to our clients. The move from GPT-5.4 to Luna illustrates that flexibility; the benchmark separately examines how the current system behaves across different sample sizes and with a stronger reasoning model. Our dependence on general-purpose models does not disappear; it becomes a choice we can manage.
This is the difference between two races. One pushes the frontier of model capability, and the whole industry benefits from it. The other is about performance in a given application: knowing which capabilities produce value there, investing in the ones that differentiate, and adopting the rest from those best placed to improve them. Gen 8 is our answer to the second.
An advantage that compounds
The billions invested in models and infrastructure will keep raising the capability available to everyone. That is good news for every company applying AI, including ours. It also means that general capability, on its own, will not set anyone apart.
"Models will keep getting better, and we want our clients to benefit from every step. What we invest in is the part that does not come with the next model: understanding each market, and the evidence behind every conclusion."
Antoine Poupel, CEO, Sensia
That is the advantage compute cannot buy.
- For brand and insights teams: Four things to demand from AI-powered consumer insights
- For AI and transformation leaders: Building AI on customer data: more data, a stronger model or a better signal?
About the tests: five production analyses (twenty sections) on three reference portfolios in skincare and pet food, regenerated with six amounts of material up to the writing model's maximum context window, plus a larger-context reasoning reference on two sections: 122 generations, October 2026. Reach measured on four questions. Main findings compared by side-by-side reading. The benchmark evaluates the Gen 8 engine in several configurations; it is not a controlled comparison with the previous generation. LLM spend on the vendor's public rate card, not the full cost of the Sensia platform.